← Research

Learning Dynamics & Optimization

How architecture, initialization and optimization shape learning.

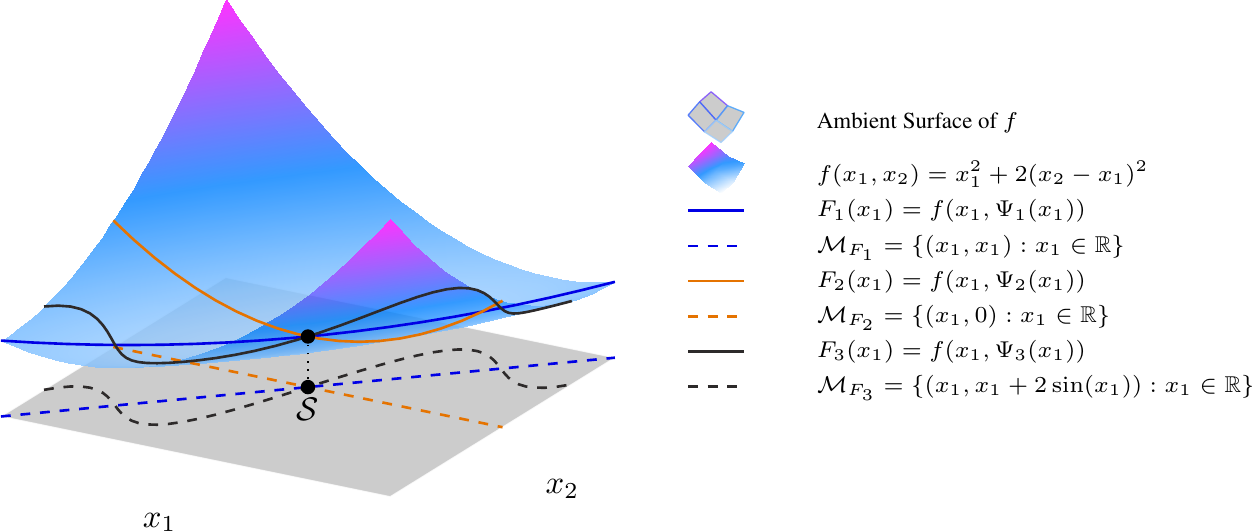
Reduction mappings change the curvature of an optimization landscape

2026

NeurIPS

AsyncMesh: Fully Asynchronous Optimization for Data and Pipeline Parallelism

T. Ajanthan, S. Ramasinghe, G. Avraham, H. Mohaghegh Dolatabadi, C. P. Hewa Koneputugodage, V. Shevchenko, Y. Zuo, A. Long

PDFarXivCode
BibTeX
@inproceedings{ajanthan_asyncmesh_arxiv26,
  title={{AsyncMesh: Fully Asynchronous Optimization for Data and Pipeline Parallelism}},
  author={Ajanthan, Thalaiyasingam and Ramasinghe, Sameera and Avraham, Gil and Mohaghegh Dolatabadi, Hadi and P Hewa Koneputugodage, Chamin and Shevchenko, Violetta and Zuo, Yan and Long, Alexander},
  year={2026},
  booktitle={NeurIPS}
}
NeurIPS

Communication-Efficient LLM Adaptation over Decentralized GPU Meshes

S. Ramasinghe, S. Siriwardhana, T. Ajanthan, H. Mohaghegh Dolatabadi, C. P. Hewa Koneputugodage, G. Avraham, V. Shevchenko, J. Snewin, K. Pajak, H. Xi, A. Long

PDFarXiv
BibTeX
@inproceedings{ramasinghe_llm_adaptation_arxiv26,
  title={{Communication-Efficient LLM Adaptation over Decentralized GPU Meshes}},
  author={Ramasinghe, Sameera and Siriwardhana, Shamane and Ajanthan, Thalaiyasingam and Mohaghegh Dolatabadi, Hadi and P Hewa Koneputugodage, Chamin and Avraham, Gil and Shevchenko, Violetta and Snewin, James and Pajak, Karol and Xi, Harry and Long, Alexander},
  year={2026},
  booktitle={NeurIPS}
}
NeurIPS

NuMuon: Nuclear-Norm-Constrained Muon for Compressible LLM Training

H. Mohaghegh Dolatabadi, T. Ajanthan, S. Ramasinghe, C. P. Hewa Koneputugodage, S. Siriwardhana, V. Shevchenko, K. Pajak, J. Snewin, G. Avraham, A. Long

PDFarXiv
BibTeX
@inproceedings{dolatabadi_numuon_arxiv26,
  title={{NuMuon: Nuclear-Norm-Constrained Muon for Compressible LLM Training}},
  author={Mohaghegh Dolatabadi, Hadi and Ajanthan, Thalaiyasingam and Ramasinghe, Sameera and P Hewa Koneputugodage, Chamin and Siriwardhana, Shamane and Shevchenko, Violetta and Pajak, Karol and Snewin, James and Avraham, Gil and Long, Alexander},
  year={2026},
  booktitle={NeurIPS}
}
ICLR

Taming Curvature: Architecture Warm-up for Stable Transformer Training

S. Ramasinghe, T. Ajanthan, H. Mohaghegh Dolatabadi, C. P. Hewa Koneputugodage, G. Avraham, V. Shevchenko, Y. Zuo, K. Pajak, A. Long

PDFarXiv
BibTeX
@inproceedings{ramasinghe_archwp_iclr26,
  title={{Taming Curvature: Architecture Warm-up for Stable Transformer Training}},
  author={Ramasinghe, Sameera and Ajanthan, Thalaiyasingam and Mohaghegh Dolatabadi, Hadi and P Hewa Koneputugodage, Chamin and Avraham, Gil and Shevchenko, Violetta and Zuo, Yan and Pajak, Karol and Long, Alexander},
  year={2026},
  booktitle={ICLR}
}
arXiv

Agora: Collective and Permissionless Internet-Scale Pretraining of Large Language Models

G. Avraham*, V. Shevchenko*, H. Mohaghegh Dolatabadi*, K. Pajak*, J. Snewin, H. Xi, R. O'Donnell, T. Ajanthan, S. Ramasinghe, C. Hewa Koneputugodage, S. Siriwardhana, A. Long

PDFarXivCode
BibTeX
@article{avraham_agora_arxiv26,
  title={{Agora: Collective and Permissionless Internet-Scale Pretraining of Large Language Models}},
  author={Avraham, Gil and Shevchenko, Violetta and Mohaghegh Dolatabadi, Hadi and Pajak, Karol and Snewin, James and Xi, Harry and O'Donnell, Rodney and Ajanthan, Thalaiyasingam and Ramasinghe, Sameera and Hewa Koneputugodage, Chamin and Siriwardhana, Shamane and Long, Alexander},
  year={2026},
  journal={arXiv},
  eprint={2607.13332},
  archiveprefix={arXiv},
  url={https://arxiv.org/abs/2607.13332}
}

2025

ICLR Workshop

Exploring Asynchronism in SWARM Parallelism

Y. Zuo, G. Avraham, T. Ajanthan, S. Ramasinghe, A. Long

PDF
BibTeX
@inproceedings{zuo_asyncswarm_iclr25,
  title={{Exploring Asynchronism in SWARM Parallelism}},
  author={Zuo, Yan and Avraham, Gil and Ajanthan, Thalaiyasingam and Ramasinghe, Sameera and Long, Alexander},
  year={2025},
  booktitle={ICLR Workshop: Modularity for Collaborative, Decentralized, and Continual Deep Learning}
}
ICLR Workshop

Momentum Look-Ahead for Asynchronous Distributed Low-Communication Training

T. Ajanthan, S. Ramasinghe, G. Avraham, Y. Zuo, A. Long

PDF
BibTeX
@inproceedings{ajanthan_mla_iclr25,
  title={{Momentum Look-Ahead for Asynchronous Distributed Low-Communication Training}},
  author={Ajanthan, Thalaiyasingam and Ramasinghe, Sameera and Avraham, Gil and Zuo, Yan and Long, Alexander},
  year={2025},
  booktitle={ICLR Workshop: Modularity for Collaborative, Decentralized, and Continual Deep Learning}
}

2024

2023

2021

ICLR

Calibration of Neural Networks using Splines

K. Gupta, A. Rahimi, T. Ajanthan, T. Mensink, C. Sminchisescu, R. Hartley

PDFarXiv
BibTeX
@inproceedings{gupta_spline_iclr21,
  title={{Calibration of Neural Networks using Splines}},
  author={Gupta, Kartik and Rahimi, Amir and Ajanthan, Thalaiyasingam and Mensink, Thomas and Sminchisescu, Cristian and Hartley, Richard},
  year={2021},
  booktitle={ICLR}
}

2020

arXiv

Post-hoc Calibration of Neural Networks

A. Rahimi, K. Gupta, T. Ajanthan, T. Mensink, C. Sminchisescu, R. Hartley

PDFarXiv
BibTeX
@article{rahimi_glayers_arxiv20,
  title={{Post-hoc Calibration of Neural Networks}},
  author={Rahimi, Amir and Gupta, Kartik and Ajanthan, Thalaiyasingam and Mensink, Thomas and Sminchisescu, Cristian and Hartley, Richard},
  year={2020},
  journal={arXiv},
  eprint={2006.12807},
  archiveprefix={arXiv},
  url={https://arxiv.org/abs/2006.12807}
}

2019