← Research

Neural Network Compression

Quantization, pruning, and low-rank methods for efficient neural networks.

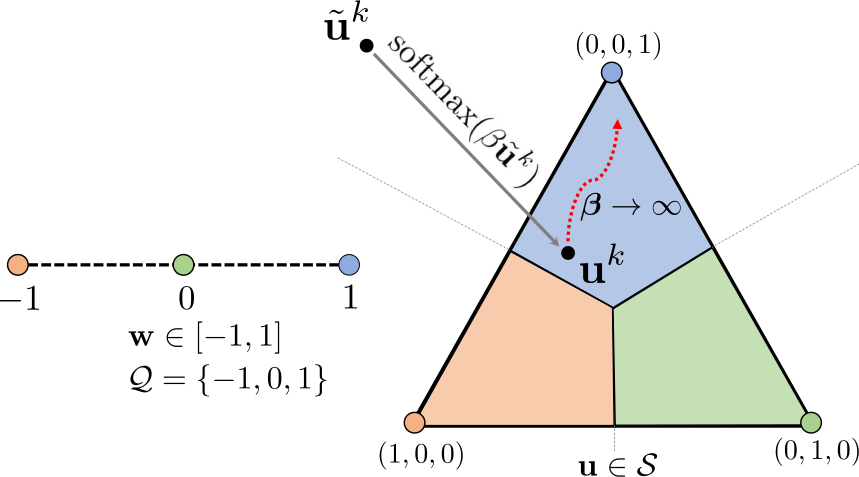
Proximal mean-field quantization on a simplex

2026

NeurIPS

NuMuon: Nuclear-Norm-Constrained Muon for Compressible LLM Training

H. Mohaghegh Dolatabadi, T. Ajanthan, S. Ramasinghe, C. P. Hewa Koneputugodage, S. Siriwardhana, V. Shevchenko, K. Pajak, J. Snewin, G. Avraham, A. Long

PDFarXiv
BibTeX
@inproceedings{dolatabadi_numuon_arxiv26,
  title={{NuMuon: Nuclear-Norm-Constrained Muon for Compressible LLM Training}},
  author={Mohaghegh Dolatabadi, Hadi and Ajanthan, Thalaiyasingam and Ramasinghe, Sameera and P Hewa Koneputugodage, Chamin and Siriwardhana, Shamane and Shevchenko, Violetta and Pajak, Karol and Snewin, James and Avraham, Gil and Long, Alexander},
  year={2026},
  booktitle={NeurIPS}
}

2025

NeurIPS

Mixtures of Subspaces for Bandwidth Efficient Context Parallel Training

S. Ramasinghe, T. Ajanthan, H. Mohaghegh Dolatabadi, G. Avraham, V. Shevchenko, Y. Zuo, C. P. Hewa Koneputugodage, A. Long

PDFarXiv
BibTeX
@inproceedings{ramasinghe_mixtures_neurips25,
  title={{Mixtures of Subspaces for Bandwidth Efficient Context Parallel Training}},
  author={Ramasinghe, Sameera and Ajanthan, Thalaiyasingam and Mohaghegh Dolatabadi, Hadi and Avraham, Gil and Shevchenko, Violetta and Zuo, Yan and P Hewa Koneputugodage, Chamin and Long, Alexander},
  year={2025},
  booktitle={NeurIPS}
}
NeurIPS

Subspace Networks: Scaling Decentralized Training with Communication-Efficient Model Parallelism

S. Ramasinghe, T. Ajanthan, G. Avraham, Y. Zuo, A. Long

PDFarXiv
BibTeX
@inproceedings{ramasinghe_protocol_neurips25,
  title={{Subspace Networks: Scaling Decentralized Training with Communication-Efficient Model Parallelism}},
  author={Ramasinghe, Sameera and Ajanthan, Thalaiyasingam and Avraham, Gil and Zuo, Yan and Long, Alexander},
  year={2025},
  booktitle={NeurIPS}
}

2022

2021

2020

2019